Building Artios
Background
Generative enzyme design is usually set up as motif scaffolding. The catalytic geometry is specified as a small set of atoms, typically the reacting atoms of the substrate and a few side-chain atoms of each catalytic residue, and a model generates a protein that holds these atoms in the specified arrangement. Within the last two years, huge leaps have been made in this space, with RFdiffusion2 (RFD2) introducing unindexed atom-level motif scaffolding, and then RFdiffusion3 (RFD3) and Proteina-Complexa (Complexa) building on this work, enabling all-atom generation for complexes with ligands and other molecules. The field and its progress have been incredibly exciting to witness.
With the arrival of these models came a benchmark, first introduced in the RFD2 paper, called AME (Atomic Motif Enzyme). AME assesses a system’s ability to design a protein whose sequence will recapitulate a specified motif. Here, recapitulation is defined as a set of criteria that centre on folding: does the sequence fold into the correctly shaped backbone? Do the catalytic residues fold into the specified geometry? Does the ligand, when co-folded with the sequence, clash with any atom in the protein?
RFD3 and Complexa have been leading this benchmark since their release, and simultaneously introduced the notion of co-design, which, intuitively, jointly generates the protein backbone with its sequence. For several years now, protein design has been split into two stages: the backbone is generated first, and the sequence after. Following the success of RFdiffusion, there have been many (diffusion-based) backbone generative models over the last ~4 years, including Chroma, Genie 2, Proteina, RFD2, RFD3 and Complexa. Sequence design, however, has not had such luck. ProteinMPNN and its ligand-aware variant, LigandMPNN, have been robust to the rapidly changing field and are found in most design campaigns, from binders (BindCraft) to antibodies (RFantibody) and enzymes (RFD2). Even though strides have been made in co-design, to the best of our knowledge it remains to be shown, either experimentally or in silico, that co-design is a more effective technique than the two-stage approach (backbone, then sequence).
The usually quiet space of sequence design was finally stirred by the 2025 Caliby paper, which built on the Potts-based method introduced by ChromaDesign (part of Chroma). The Caliby authors demonstrated that their method could generate consistently more “foldable” sequences than the autoregressively trained ProteinMPNN. By using a Potts head, Caliby takes an initial sequence through many rounds of mutations, minimising an energy function that is inferred from the protein backbone. Caliby was not presented with experimental validation, nor was there evidence that this approach could extend to protein–ligand complexes, which enzyme design requires.
Our approach
Inspired by the interesting work in the field, we decided to tackle the de novo enzyme design problem. Our development went through many phases, but the final system pivoted on addressing the following key questions:
- How should we perform motif scaffolding? And how do we evaluate whether our system is good at the task?
- How should we design our sequences? Do we perform co-design, or do we take a two-stage approach?
- How can we build the infrastructure required to develop and deploy these models without access to a large GPU cluster?
We opted for a two-stage system, consisting of a motif-scaffolding backbone model, ArtiosBackbone, and a Potts-based, ligand- and active-site-aware sequence design model, ArtiosPotts. We evaluated our system on a variant of the AME benchmark that additionally assesses ligand positioning, and we built a high-throughput design system natively on Modal.
This system allowed us to design multiple active luciferases and esterases in the lab and demonstrates SOTA performance on AME (Figure 5), as well as on our proposed AME variant. ArtiosPotts in particular beats LigandMPNN in all factors relevant for modern protein design pipelines, covering folding confidence and consistency, and ligand awareness (Figure 8), and does this whilst maintaining more natural, complex sequences (Figure 7). We dedicate the rest of this blog to diving deeper into our design decisions.
1. Motif scaffolding
The model
ArtiosBackbone generates a protein backbone together with its ligand around an atom-level active-site motif, and does not co-design a sequence. It is a diffusion transformer with an attention bias computed from pair features, similar to the diffusion module of AlphaFold 3 and to Proteina, and it has no Pairformer, triangle updates or sequence track (Figure 2). Each backbone residue and every heavy atom of the ligand and of the motif is treated as its own token. ArtiosBackbone does not get handed the sequence positions of the catalytic residues, enabling unindexed motif scaffolding. Our diffusion trajectories use self-conditioning but do not use any guidance. The model is lightweight: it trains in just over 24 hours on a single node of eight A100 GPUs.
The benchmark
In order to reliably improve on our models during development, we need a benchmark that quantifies the properties that we want. This is especially important in the case of the generative modelling of enzyme backbones because, unlike the usual scaling laws of deep learning (Kaplan et al., 2020; Hoffmann et al., 2022; Gadre et al., 2025), we never observed that downstream performance could be predicted from the training loss alone. In fact, we saw that many properties behaved very unexpectedly during training, the most blatant being structural diversity, which we often saw undergo grokking-style behaviour (Power et al., 2022; Figure 3).
Grokking behaviour was not consistent across all of the models that we trained, but what was consistent was that we struggled to determine behavioural differences between our models, or even between our checkpoints, without computing an extensive eval. The choice of eval is arguably the most important choice we made in the whole development period. For enzyme design, we need to balance making diverse proteins that are highly “foldable” and that also create suitable pockets for ligands. The most obvious first choice of eval for enzyme design is AME. The AME criteria (Ahern et al., 2026) are a sensible test of whether a design folds as intended, and they are frequently used in the literature, often with slight variations (Butcher et al., 2025, Didi et al., 2026, Wu et al., 2026). But in the criteria there is no measurement that assesses the quality of the pocket made for the ligand. This is not picked up by the motif all-atom RMSD, which will frequently report correct motif recapitulation whilst the ligand moves to a very different location after co-folding (Figure 4).
Given the importance of the ligand’s pocket to enzyme design, we used an alternative for our development, additionally requiring that the ligand’s centroid does not deviate greatly between the co-folded structure and the proposed design. Concretely, we co-fold the designed sequence with its ligands using Protenix and superpose the co-fold onto the design on the Cα atoms of the pocket residues. A design then passes only if, for every ligand \(\ell\),
$$\left\lVert \bar{\mathbf{y}}_\ell - \bar{\mathbf{x}}_\ell \right\rVert < 3\ \text{Å},$$
where \(\bar{\mathbf{x}}_\ell\) and \(\bar{\mathbf{y}}_\ell\) are the centroids of the atoms of ligand \(\ell\) in the design and in the superposed co-fold, respectively. This has a large impact on the pass rates (Figure 5). Balancing foldability, ligand awareness and diversity remains a hard challenge for generative models in the space. The protein design field is familiar with experiencing low pass rates when it comes to performing actual campaigns, but this is an equally vital aspect when benchmarking during model development, since low pass rates require a large volume of designs to increase the signal-to-noise ratio of measurements, which is a necessary criterion for hill-climbing a model’s performance.
Now armed with a more appropriate benchmark, we found it much easier to make firm conclusions about what does and doesn’t improve performance. There were many things we tried along the way, but the following points had the largest impact:
- AME success rates were greatly improved by being able to specify where the motif should lie in the protein. For our models, this takes the form of extra features: a “motif depth” feature, as well as a “burial” feature that we can apply atom-wise to the substrate. Similar features exist in models such as RFD3, which can be conditioned on the solvent accessibility of individual ligand atoms as well as the centre of mass (CoM) of the motif relative to that of the design (Butcher et al., 2025). Not only does this unlock flexibility in the types of pocket we generate during campaigns, but specifying that the ligand should be buried deep in the protein generally improves performance across the 41 AME inputs. Without these features, we would often see that the model preferred not to place the ligand in a pocket. We attempted to solve this with data engineering alone, which we think is a more satisfying direction, but it did not match the performance and flexibility benefits at design time that these features provide.
- Data engineering of single-chain distillation datasets provided no improvement in AME success rates, and was often detrimental. This was a tough pill to swallow, because the bitter lesson part of our brain greatly encouraged us to scale up our training dataset beyond just the PDB, but no matter the tricks we used, ranging from sophisticated pocket detection techniques to spectral-based domain identification, we did not find that this was beneficial for designing enzymes. We would love to see others in the field demonstrably prove, via controlled ablations, the benefits of distillation datasets for enzyme design.
2. Sequence design
The main reason we opted for the two-stage approach was that we found Caliby’s work, which builds on ChromaDesign, very exciting. We saw there was a chance for a step-change in sequence design for enzymes and, given how actual design campaigns have such an emphasis on rounds of repeated sequence design, it felt like it addressed a true bottleneck.
Caliby and ChromaDesign use a Potts model instead of the usual per-residue logit readout used for autoregressive sampling in ProteinMPNN and LigandMPNN. The fundamental difference here is that a Potts head, outputs per-residue fields \(h_i\) and couplings \(J_{ij}\) over each pair of residues, which can be used to define an energy function over all possible sequences for a given backbone. Potts models are a well-established method used in structural biology for analysing families of sequences. In direct coupling analysis, for example, Potts models fitted to multiple sequence alignments can be used to predict which residues are in contact (Morcos et al., 2011; Ekeberg et al., 2013) and the effects of mutations (Hopf et al., 2017), and can even be sampled from to generate active enzymes (Russ et al., 2020). In Caliby and ChromaDesign, the Potts model is used for mutation-based sampling: a sequence is optimised over many rounds of mutations (using a variant of MCMC) to minimise the learnt energy function.
There are two main problems with sequence design models. The first is that they often do not work. That is, for example, a ProteinMPNN sequence will often not fold into the backbone it was designed for. This isn’t always a problem, because MPNN inference is very cheap, and one can boost one’s success rate by designing multiple sequences, eventually finding a sequence that does fold into the correct shape. But given that this necessitates folding, which is not cheap, we are motivated to increase the per-sequence folding success rate. The other problem, which the computational protein design field is often critiqued for, is that the sequences that sequence models output do not look natural (Figure 7). Given that ProteinMPNN and LigandMPNN finally enabled protein designers to actually design sequences that could work in the lab, this has been less of a priority, but most in the field will easily be able to identify the characteristic low complexity of MPNN-based sequences as well as the long strings of hydrophobics and incredibly strong preference for alanines.
Caliby demonstrated to us that a Potts model could solve both of these problems. They demonstrated that Potts-based sequences have a much greater folding success rate. Additionally, they use the local composition perplexity (LCP) penalty introduced in ChromaDesign, which, as the name suggests, encourages local windows in the sequence to not collapse in perplexity, translating to more complex sequences, ultimately looking more “natural”.
It remained to be seen whether or not this in silico success would translate to enzymes, or even whether or not these sequences would express in the lab. But given the results, we were very eager to try. This led us to develop ArtiosPotts, a Potts-based, ligand- and motif-aware sequence design model. Like the other models in the literature, ArtiosPotts uses a GNN to encode the complex and passes its embeddings to the Potts head. It differs from LigandMPNN in that it uses a single protein–ligand–motif graph instead of separate protein, ligand and protein–ligand graphs. We train on the AlphaFold 3 PDB dataset splits and complete training within 3 hours on 2 A100s.
Like Caliby, we saw massively improved folding success rates (Figure 8A). Our AME scores also greatly improved: on the same RFD3 backbones, replacing LigandMPNN with ArtiosPotts raised the pass rate with ligand retention from 0.9% to 5.3% (Figure 8B), which indicated that the Potts-based approach extends to protein–ligand complexes. To decouple whether or not the success was limited to de novo backbones, we wanted to test how ArtiosPotts performed relative to LigandMPNN on a set of natural protein–ligand complexes. We extracted 114 complexes from the AF3 evaluation set which were dissimilar in sequence to the training set and contained at least one buried ligand. We call this dataset SeqVal. Success on SeqVal means designing a sequence that folds into the natural backbone and, like in our AME variant, keeps the ligand in its original position. We find that ArtiosPotts is superior here, more than tripling the success rate over LigandMPNN (Figure 8C).
We also quickly saw success in the lab. We first identified that ArtiosPotts sequences express strongly, and usually more strongly than LigandMPNN sequences. We tested this by taking seven natural backbones from the PDB across a range of diverse secondary structures, designing 10 sequences with each model and expressing all of them in a cell-free system, measuring expression by HiBiT luminescence (Figure 9). We explain this experiment in more detail in the section “ArtiosPotts sequences show higher cell-free expression than LigandMPNN sequences” of our paper.
More excitingly, however, we show that ArtiosPotts can successfully design de novo enzymes with our fully de novo luciferases and esterases. The computational aspect of these campaigns was made much easier with ArtiosPotts’ increased in silico success rates, enabling much more stringent in silico filters to get our final 96.
We are very excited about the use of Potts models for enzyme design and feel like we have only scratched the surface. Since the model can be trained so quickly, it can be easily hill-climbed (given an appropriate eval). The time bottleneck for developing the model was on evaluating its performance, instead of training it. Additionally, the MCMC-based sampling method is highly flexible: since one always has access to a global sequence state, it is easy to guide the sequence distribution, locally or globally, towards almost anything. And surprisingly, the outputted sequences, when guided according to some objective, can remain highly foldable. We initially saw this with the LCP penalty from ChromaDesign, which not only succeeds in increasing sequence perplexity, but also increases folding success rates. This was an eye-opening observation for us as it opens the door to other guidance methods that allow the user to optimise for whatever property they like whilst ensuring that the sequences remain sensible. We will release more work on the use of guidance in Potts models in an upcoming blog post.
We believe there is much more work that can be done to improve sequence design and that the field should not settle for older methods or altogether abandon it in favour of more elegant solutions.
3. Infrastructure
De novo design pipelines usually have very low hit rates. Better models, as well as more compute and more sophisticated systems, have meant that certain modalities in the field have recently made jumps here. Binder design methods such as AlphaProteo and BindCraft report experimental success rates of 9–88% and 10–100% per target (Zambaldi et al., 2024; Pacesa et al., 2025), and in antibody design, where RFantibody reported per-target success rates of 0–2% (Bennett et al., 2025), Chai-2 found binders for half of 52 targets while testing at most 20 designs per target (Chai Discovery Team, 2025). But for enzyme campaigns, especially those that do not rely on reactive cofactors, experimental hit rates remain low.
The usual solution to low hit rates is scale: either scale the number you are testing in the lab, or scale the in silico screening by generating more designs, allowing for harsher in silico filters and thus better candidates to test. But the low hit rates the field currently experiences are already at the end of enormous computational pipelines, often on the scale of assessing 100k–1M sequences for a final plate of 96. Unless there is a paradigm shift in de novo design, the compute bottleneck will remain, and it will likely stay for a while.
Screening this many designs requires access to huge amounts of compute. For some of the leading institutions, this means having an internal compute cluster or renting from cloud providers. These were not viable options for us, since we are such a small team and only need access to compute relatively irregularly.
Autoscaling
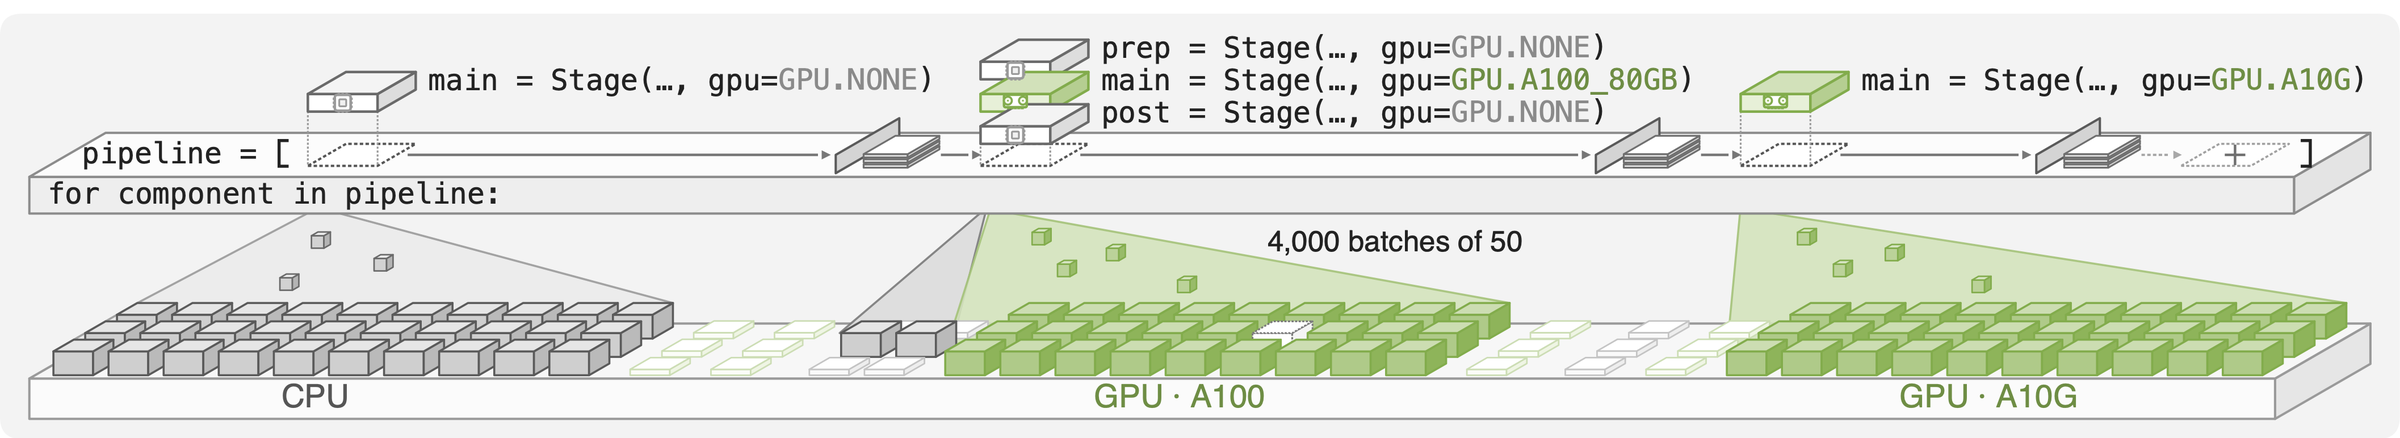
We decided to build our entire infrastructure natively on Modal, which allows us to submit very bursty jobs: we may not need to perform inference for a month, but the following month there may be a point where we need to generate 1M sequences in 12 hours. With Modal, we can “rent” the GPUs for exactly the compute time that we need, parallelising the jobs across up to 3,000 GPUs, a feature known as autoscaling (Figure 10).
Using Modal has been incredibly enabling for us and was exactly the reason why we could iterate quickly and perform huge campaigns overnight, waking up to a filtered set of 96 designs ready to order DNA for.
Batching
Modal worked perfectly for performing many jobs in parallel, but for close to 1M designs, with only 3,000 GPUs, and requiring most of those designs to be sent through many other models like AlphaFold2 and Protenix, we needed more parallelisation. We achieved this by making the entire infrastructure batch-native, meaning that every model’s inference and all downstream metric calculations work on a batch of proteins, all at the same time. This means that, on a single H200, we can create 400 backbones within 90 seconds, and design their sequences even faster. This extends to our filesystem too, massively reducing I/O by saving data in batched files, bringing the number of files we store down by a factor of hundreds.
A composable design system
In the field of protein design, it is almost always the release of a new model that captures attention, usually coming with a beaten benchmark or a new design feature. But in our experience, how one deploys the models has a far greater impact than small improvements on a benchmark. The order in which you apply the models, how you filter your designs, how many sequences you design per backbone and how you perform redesigns after folding have an enormous impact on the quality of your final designs. We have seen design campaigns drop in price by multiple orders of magnitude simply from rejigging where you allocate your compute (this work will be released in a future blog post). Examples of sophisticated system design can be found in many places in the literature (Lauko et al., 2025, Kim et al., 2026, Braun et al., 2026).
To illustrate what we mean by system design, consider the following example campaign, which looks very similar to real campaigns we have run:
- Design 100k backbones across this set of 5 motifs.
- Filter for backbones that have a good cavity for the substrate.
- Design 5 sequences for each backbone and fold each sequence with AlphaFold2.
- Filter for the backbones that have a passing sequence and design 100 more sequences for each passing backbone.
- Fold all sequences with ESMFold2 and design sequences on the folded outputs.
...and so on.
We believe that one of the keys to unlocking improved de novo enzyme design is being able to easily perform campaigns like the above, and to be able to refine the pipeline used for the campaign, often tuning it for the specific scenario. For example, for an amylase campaign, one may not need to make as many backbones, since the backbone model generates fewer unique folds than for other campaigns, and so instead we might want to allocate that compute to more redesigns.
But performing campaigns like this requires highly composable pipeline components, which is a large engineering challenge. We are open-sourcing our evaluation pipeline (code released on Friday), which we built with exactly this composable ethos in mind.
Conclusions
We built Artios, a two-stage enzyme design system that pairs ArtiosBackbone, a lightweight diffusion model for unindexed atom-level motif scaffolding, with ArtiosPotts, a ligand-aware Potts-model sequence designer, and evaluated it on a variant of AME that also requires the designed pocket to keep its ligand. Running on batch-native infrastructure built on Modal, Artios achieved state-of-the-art results on AME and produced active luciferases and esterases in the lab, with ArtiosPotts outperforming LigandMPNN both in silico and in a cell-free expression test.
Artios differs from the direction of the literature by demonstrating that, via improvements in sequence design, the two-stage design approach can produce better in silico performance than co-design. We think Potts-based sequence design models offer benefits to de novo enzyme campaigns that should not be overlooked in favour of methods that, although more scientifically satisfying, have not been shown to outperform established models like LigandMPNN. Compute bottlenecks, poor sequence design and under-optimised design systems are what are holding back the space, and we believe the literature should focus more research on these areas.
Acknowledgements
Emily Egerton-Warburton led the experimental work in the paper and designed the active-site motifs. Edward Harris ran experiments and managed the project. Arda Goreci and I built the computational system. During an internship in 2025, Carlos Vonessen wrote code for an early version of the sequence model that later became ArtiosPotts.
Citation
Please cite this post as:
Oliver Cort, "Building Artios", Ligo Biosciences Blog, October 2026.For the models and results, please cite the paper:
Ligo Biosciences Team, "Artios: Designing Functional De Novo Enzymes with
All-Atom Diffusion and Steerable Potts Models", October 2026.